
Thomson Reuters (CA): Thomson LLM Proprietary Model Shifts AI Strategy
What Happened
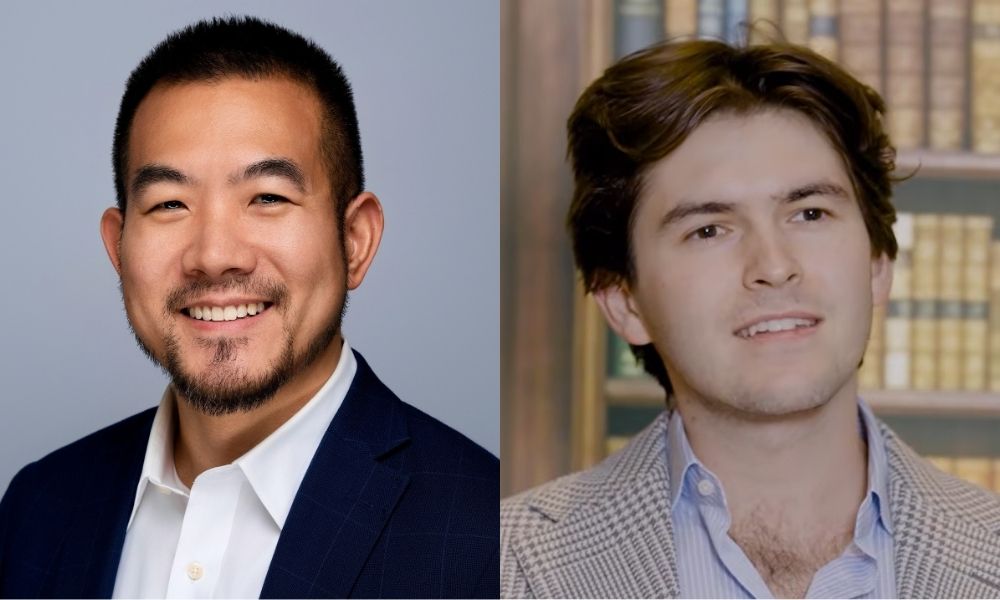
Product leads talk about why their model ranks first in class for legal factuality and gives firms a path to sovereign AI  The question of whether to buy or build AI is one that law firms across Canada are actively wrestling with. Thomson Reuters has now answered it for itself: the July 2026 launch of Thomson – its first proprietary large language model (LLM) – marks a strategic pivot away from relying solely on third-party models from providers such as OpenAI, Anthropic, and Google. Two factors drove that decision. David Wong, the company’s chief product officer, and Alexander Kardos-Nyheim, who co-leads Thomson Reuters’ foundational machine learning research, discussed the shift in a recent CL Talk podcast interview . Kardos-Nyheim came to Thomson Reuters through the 2024 acquisition of Safe Sign Technologies, a legal AI startup he founded while completing his training contract at A&O Shearman. The Thomson LLM sits within what Wong calls a multi-model strategy – selecting the best available model for each task rather than committing to one provider. The first driver for building in-house is cost. “Using the latest frontier models is the shortcut to get good performance, but they’re very expensive,” Wong says. The second is data sovereignty. As concerns about where client data is processed grow, “the amount of trust with some of the big tech vendors is declining, and some, not all, ... firms are interested in rolling their own, running their own infrastructure, using their own tech, operating models by themselves,” he says. Thomson Reuters says it is exploring options to license the Thomson model to firms that want to run it on their own hardware without external providers, though it has not yet done so. To distinguish domain-specific training from retrieval-augmented generation (RAG) – the approach most legal AI tools rely on – Kardos-Nyheim uses a pointed analogy: “I’d compare domain-specific training to RAG as a closed book versus an open book exam.” RAG supplies the model with relevant documents at inference time. Training encodes knowledge directly into the model’s parameters – a fundamentally different level of capability. The Thomson model was trained on Thomson Reuters’ content universe – Westlaw, Practical Law, and Checkpoint – and is trained on the work of thousands of lawyer-editors. On legal factuality benchmarks – the model’s ability to link a legal proposition accurately to the correct citation – the results stand out, Kardos-Nyheim says. “The model is not only first in class, but it is first in class by almost 20 points,” he says, attributing the margin to a focus on source hierarchy: “understanding that there is primary law that takes precedence.” He says the model has achieved this after seeing less than 10 percent of Thomson Reuters’ total content. “We have already managed to enhance the capabilities of this model significantly with just a small portion of what we think we have to offer,” he says. For lawyers, “fiduciary-grade” has a specific meaning. Wong says it is a system built for professionals with fiduciary responsibility to their clients, where the consequences of error are greater and accuracy, privacy, and transparency are non-negotiable. “The burden of proof for truthfulness and accuracy is higher, and privacy, security, and transparency are higher,” he says. The framework rests on four principles: grounding in authoritative sources, built-in data privacy and security, human oversight incorporating professional expertise, and transparent and verifiable reasoning. A recursive verification method – in which the system checks its own responses against cited sources to detect potential hallucinations – underpins the reliability architecture. “This recursive verification has larg
Practical Implications
This development signals a critical shift in the legal AI market, emphasizing data sovereignty, cost efficiency, and 'fiduciary-grade' accuracy. Law firms and compliance officers should re-evaluate their AI adoption strategies, considering the benefits of proprietary, domain-specific models that offer on-premise deployment options and superior factuality benchmarks, particularly when addressing client data privacy concerns and the reliability of AI outputs.
Source
How does this affect you?
Get an AI analysis of this article grounded in your jurisdictions, practice areas, and any policy documents you've uploaded to Wansom.
Finish Reading the Full Story and the Expert Analysis.
Get the latest legal & regulatory intelligence in Canada
Wansom is AI and can make mistakes.